01
One execution path rarely fits every workload
Workloads differ in quality, latency, privacy, volume, capability, and economics.
Hybrid AI infrastructure
Manthan is the inference infrastructure layer for running AI workloads across your infrastructure and model providers.
Deploy open-weight inference on infrastructure you control, while keeping your existing model providers available through the same interface.
One API. Your infrastructure. Your providers.
Clients
Claude Code
AI products
Agents
·
Manthan
Sits between
Route · policy · meter · fallback
Destinations
Your infrastructure
Anthropic
OpenRouter
OpenAI
The problem
AI workloads increasingly span model APIs, open-weight models, and dedicated infrastructure. The challenge is deciding where each workload should run, operating those paths reliably, and understanding the economics of the result.
Different workloads often share one execution strategy.
Quality needs, latency, privacy, and economics vary, but operations often treat them as one path.
Recurring traffic
VolumeWorkload mix A
Stable production traffic with defined quality and latency targets
Specialized needs
SelectiveWorkload mix B
Specialized capability, strict latency, or provider requirements
Where it all goes
Single execution strategy
One infrastructure or provider approach for mixed workloads
Result
Harder to optimize quality, reliability, and cost together
Decide where each workload should run. Operate those paths reliably, and understand the economics.
01
Workloads differ in quality, latency, privacy, volume, capability, and economics.
02
Serving runtimes, model configuration, capacity, observability, utilization, security, and failure handling have to operate as one system.
03
Provider access, infrastructure, execution policy, usage, routing, and fallback need one operational layer.
How it works
Connect once. Keep your existing providers. Add optimized inference infrastructure where it creates measurable value.
Use compatible SDKs and existing provider credentials with minimal application changes.
Evaluate quality, latency, volume, utilization, privacy, and economics at the workload level.
Run each workload through the environment that best fits its requirements while Manthan maintains policy, observability, and fallback.
Execution paths
Manthan operates across customer-controlled inference, optimized serving infrastructure, and configured model providers.
Customer-controlled
Deploy suitable open-weight workloads on customer-controlled infrastructure when control, privacy, utilization, or workload economics make dedicated inference the better fit.
Optimized inference
Run recurring workloads on serving infrastructure configured around model, latency, throughput, and capacity requirements.
Provider execution
Use frontier and serverless providers when their capability, economics, or availability make them the better execution path.
Architecture
Clients connect through one OpenAI-compatible API. Manthan applies workload policy using telemetry and economic signals, then executes across customer-controlled inference, optimized serving, and configured model providers.
Policy-driven execution
Start with explicit workload policies and add sophistication only where it creates measurable value.
Resilient execution
Maintain continuity across configured execution paths when capacity, capability, or availability changes.
Measurable economics
Track latency, failures, utilization, execution mix, and cost at the workload level.
Production infrastructure · Not a model marketplace
Workload policy · telemetry · economics
Customer-controlled
Optimized inference
Provider execution
Model providers
Platform
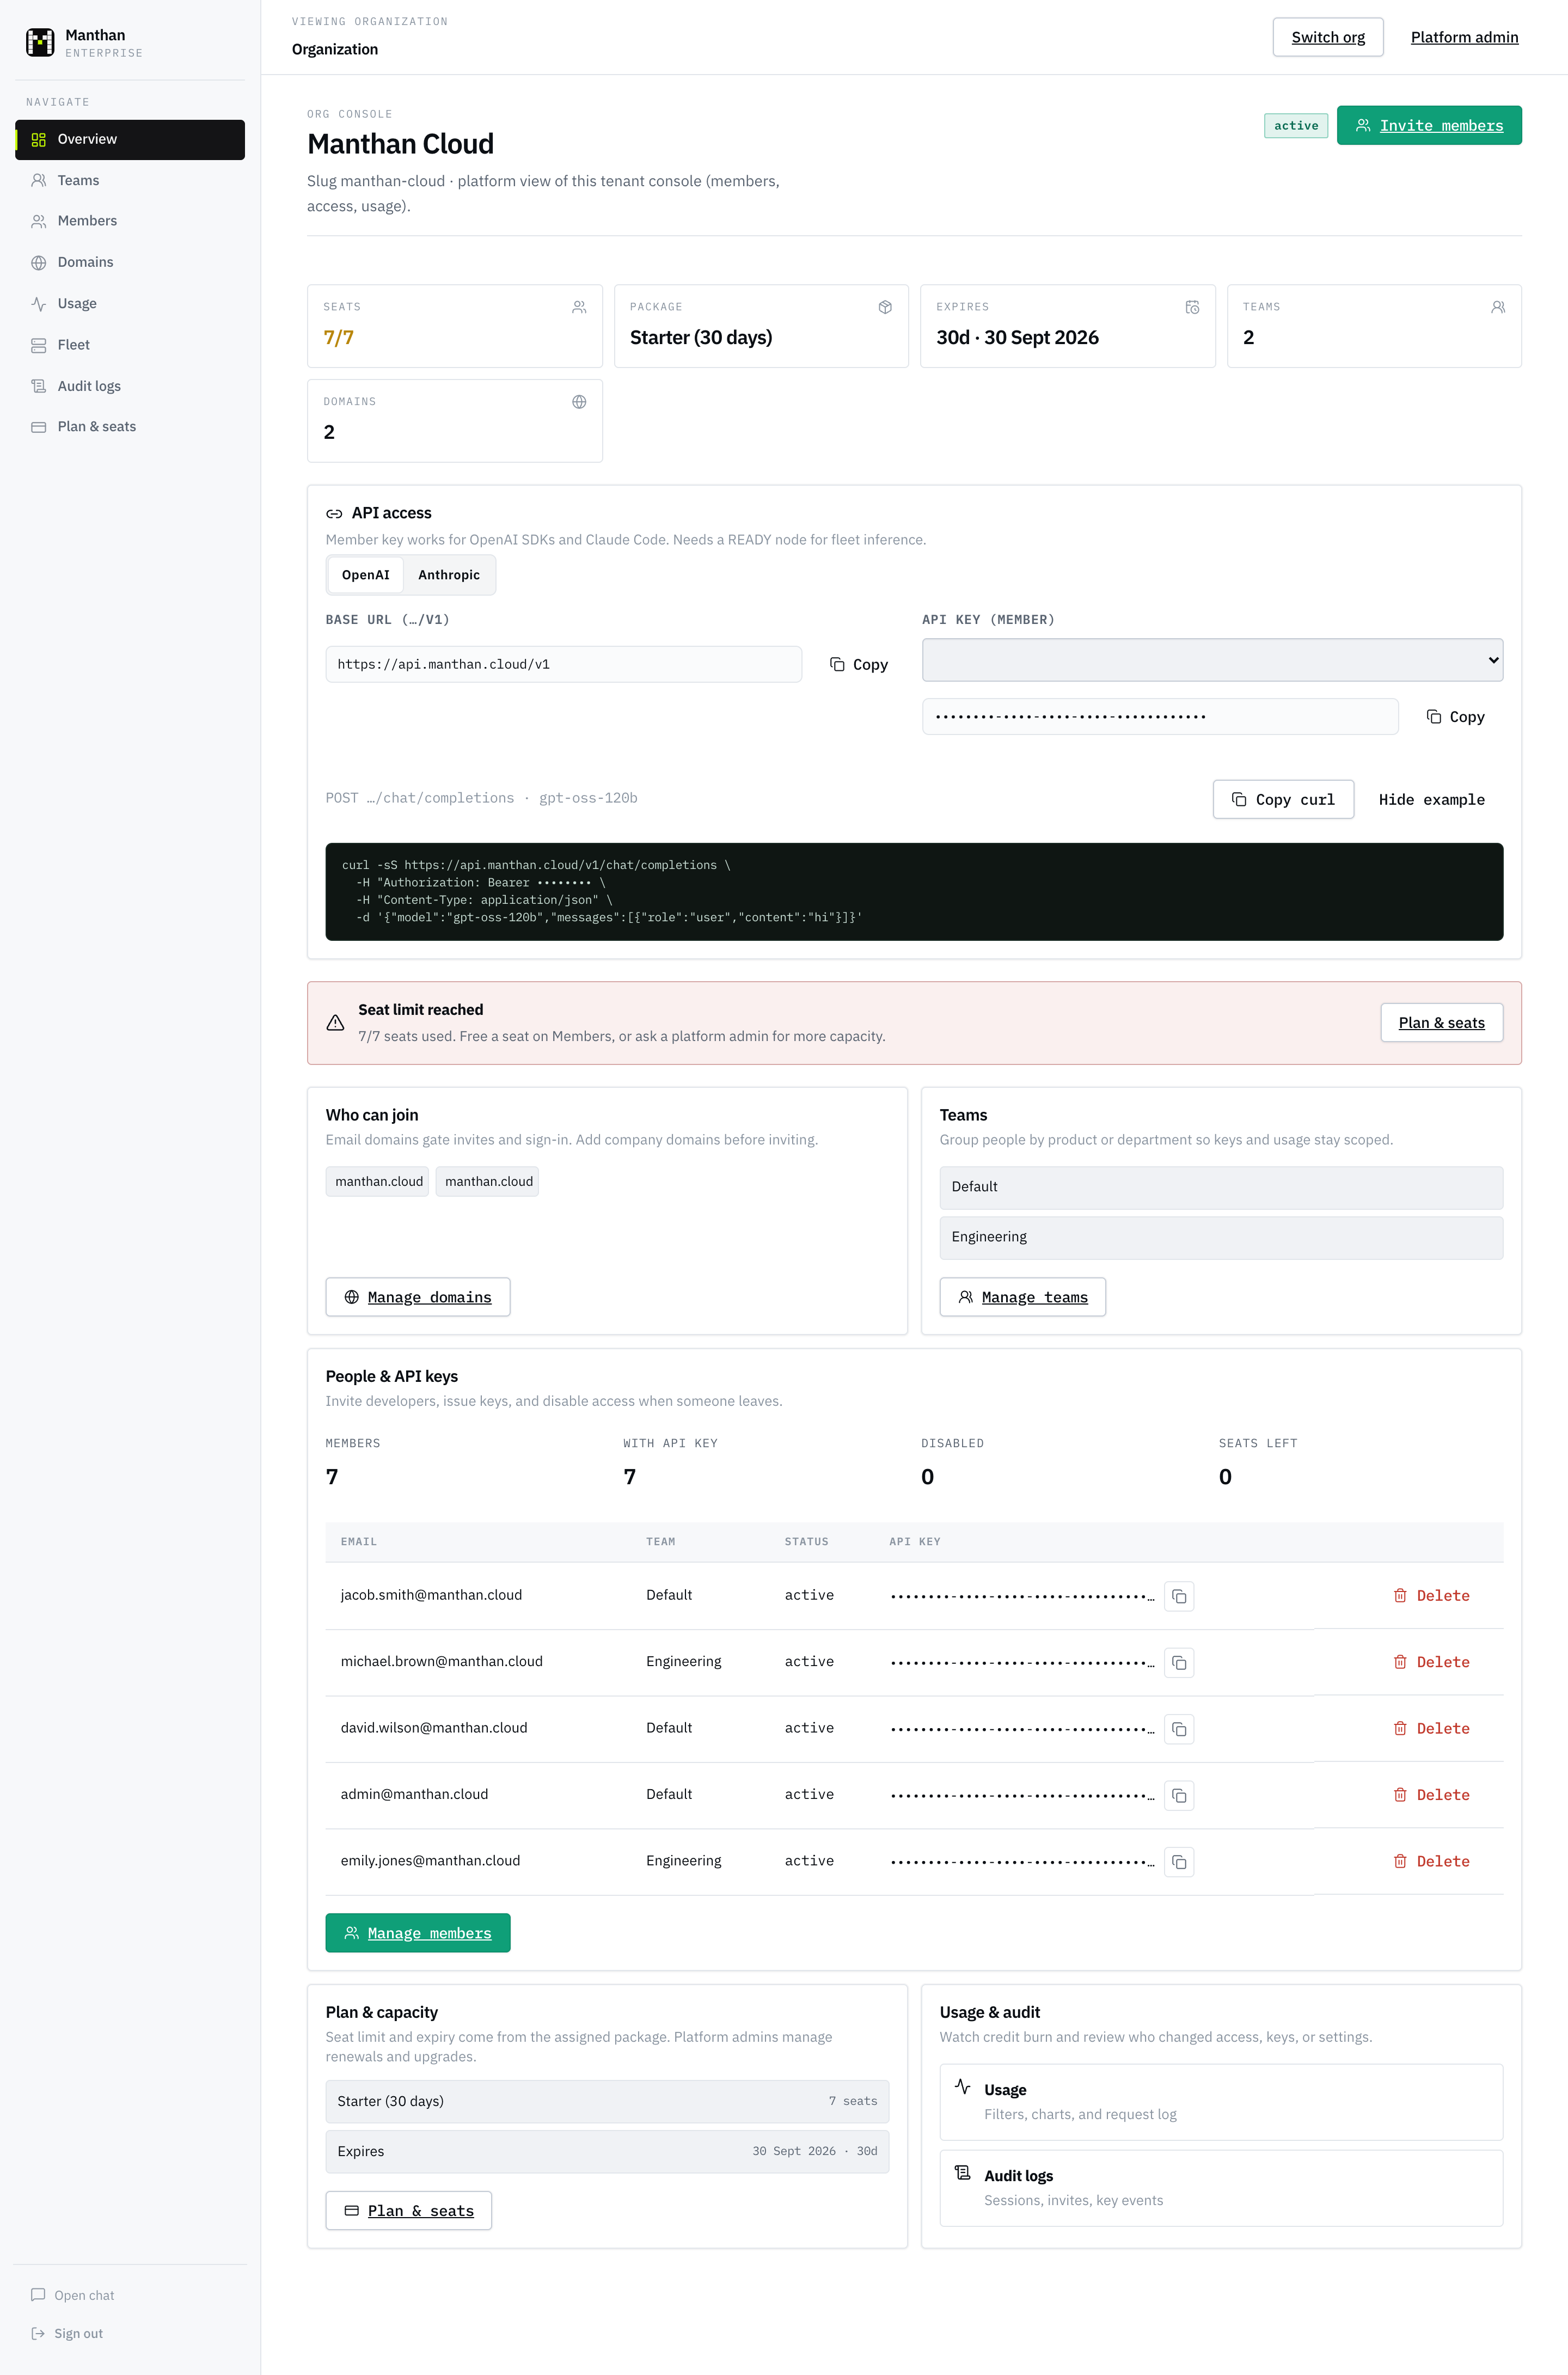
Manage inference access, infrastructure, provider connectivity, usage, and execution policy from one operational layer.
Overview
Organization home for inference configuration, access, and operational status.
Inference economics
Token price alone does not determine production economics. Manthan evaluates the total cost of delivering a successful workload outcome across model providers and infrastructure.
Ask 01
Quality and completion matter more than tokens generated.
Ask 02
Total spend for that outcome across model providers and infrastructure.
Ask 03
Latency, failures, and fallback, not just unit price.
Primary metric · cost per successful task
Today
Mixed workloads often share one infrastructure or provider approach, so blended economics stay hard to read.
Illustrative execution mix
With Manthan
Route workloads according to their requirements and measure economics across the execution mix.
Example only. Actual execution mix depends on workload requirements and economics.
Infrastructure economics estimator
Model how workload mix, volume, and infrastructure assumptions affect blended inference economics.
What that could mean
Illustrative estimate only. Actual economics depend on workload characteristics, quality requirements, model selection, infrastructure utilization, provider pricing, and fallback behavior.
Why Manthan
01
Optimize around workload requirements rather than tying every request to the same model or infrastructure strategy.
02
Evaluate provider cost, infrastructure utilization, latency, reliability, and workload outcomes as one system.
03
Use customer-controlled infrastructure, optimized inference, or existing model providers through one operational layer.
Who it is for
Operate production inference across infrastructure and providers without rebuilding integrations as the execution mix evolves.
Centralize access, capacity, usage, and execution policy so infrastructure decisions remain measurable and resilient.
Manage inference as a production system as AI becomes a meaningful component of product infrastructure and cost.
Next step
Tell us your stack and the workload you want to optimize. Manthan helps determine the right execution path and deploy the required inference infrastructure while keeping your existing providers in place.